Catch RAG regressions before users do
ragproof is a framework-agnostic Python CLI that calls a deployed RAG API, records versioned evidence, computes retrieval and citation metrics, and turns quality thresholds into CI exit codes.
It is designed for a common failure mode: a prompt, chunking, retriever, or model change still returns HTTP 200 while answer quality quietly gets worse.
Run the offline quickstart Inspect the public benchmark Configure an adapter
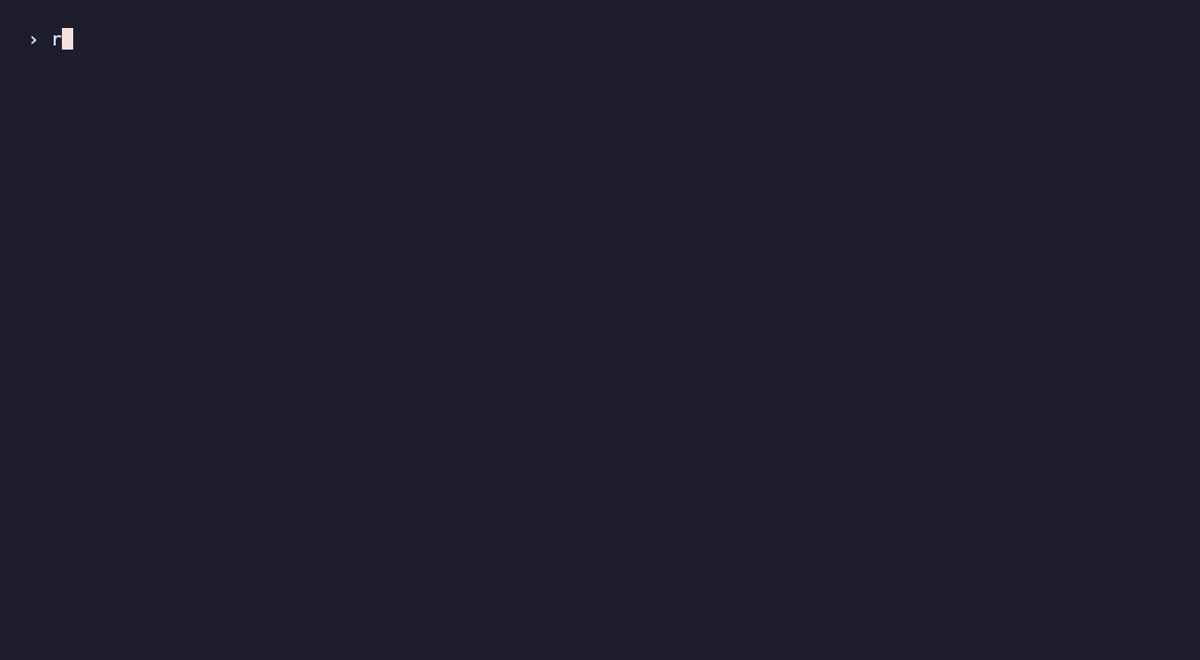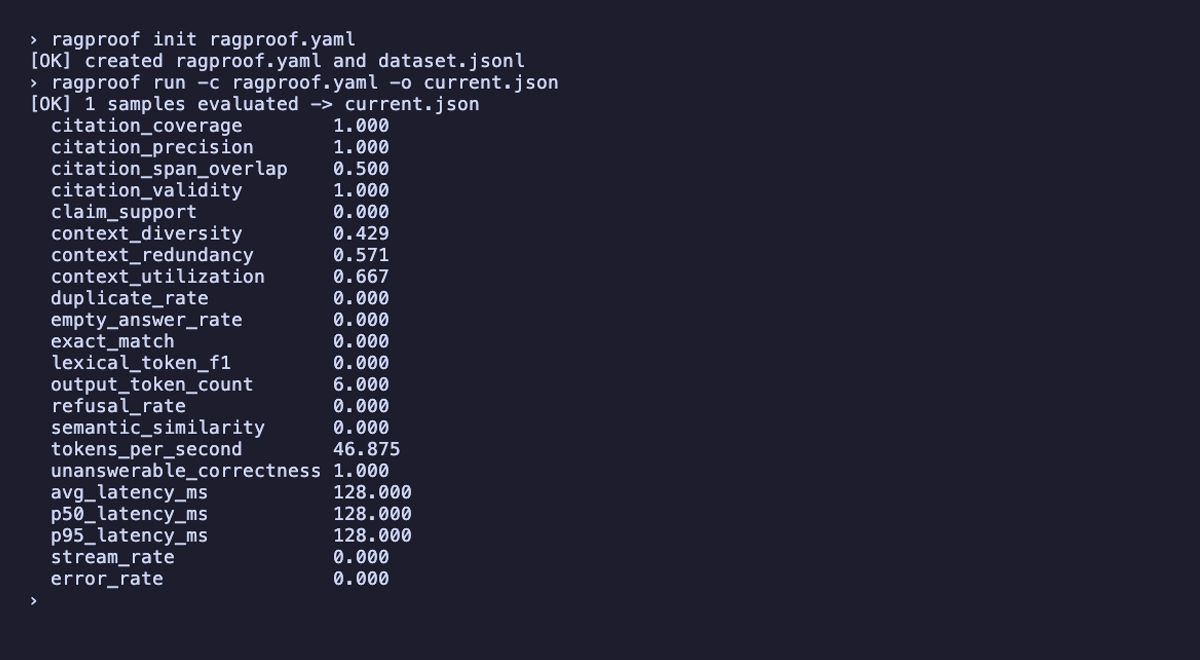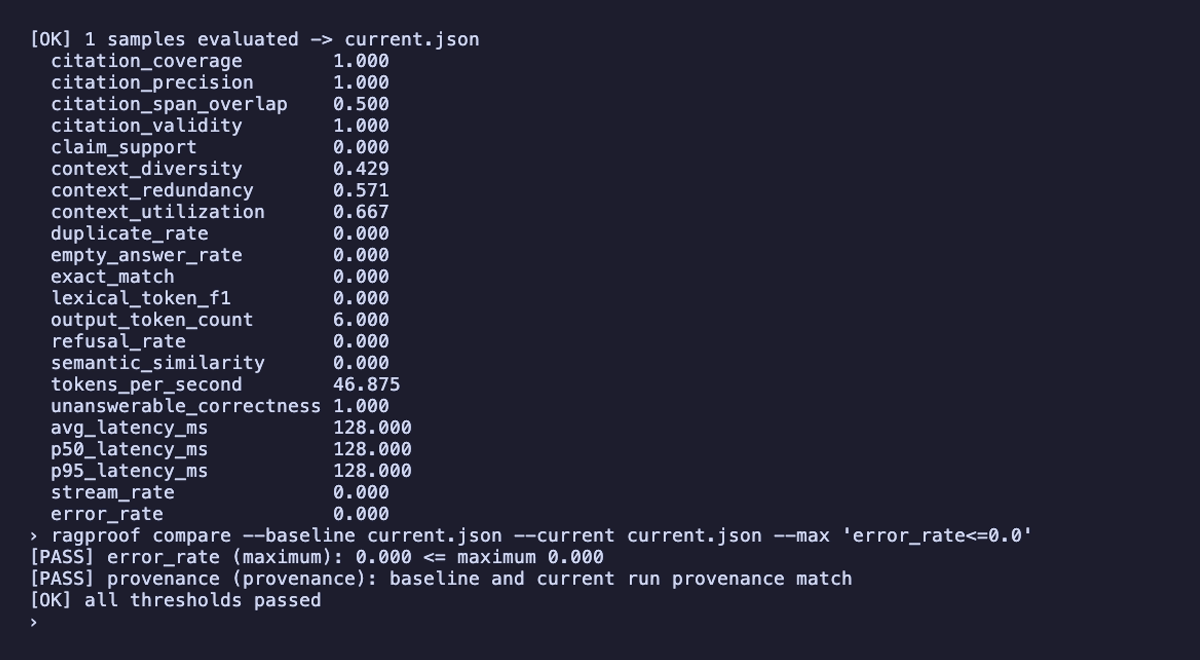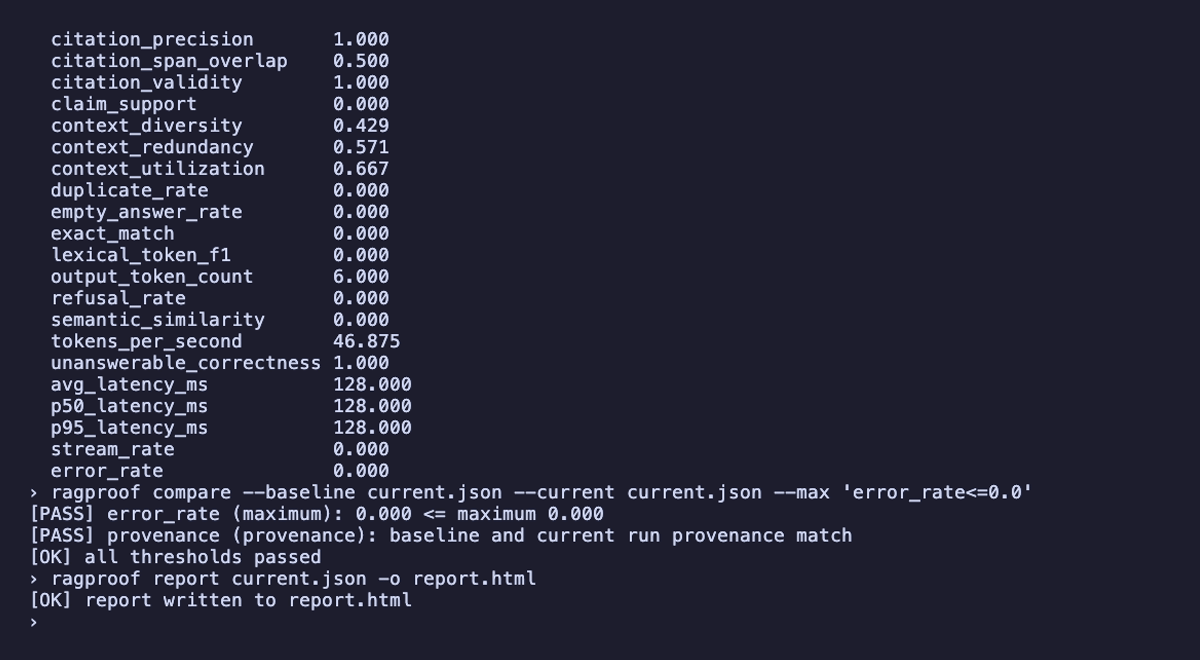
The recording uses the deterministic mock adapter to demonstrate the CLI workflow. The evidence below comes from the separate public HTTP benchmark.
Reproducible HTTP contract benchmark
The repository ships a known-good baseline produced through the real generic HTTP adapter, not the in-process mock. The corpus, questions, service, configuration, hashes, and negative controls are all checked in and run without a model or external network call. The summary below is regenerated from the same current run as the full published report.
The current run has 55/60 samples with context (91.7%); deliberately unanswerable samples return no context or citation by design. The complete report records commit 3a6b7efe283b5273bb7e58c56057636d8f367bb1, fingerprints, all metric coverage, group slices, and per-sample evidence.
Two separate negative controls prove that shuffled ranking and missing citations fail their intended gates.
What these numbers mean
This synthetic, deterministic benchmark validates adapter mapping, metrics, citations, provenance, and CI failure behavior. It does not measure production RAG quality or compare model vendors.
Open the current full report · Read the method and limitations · Inspect the committed baseline
From API response to merge gate
flowchart LR
  D[Dataset] --> A[HTTP / mock adapter]
  A --> E[Answer + contexts + citations]
  E --> M[Deterministic metrics]
  E --> J[Optional LLM judge]
  M --> R[Versioned run JSON]
  J --> R
  R --> C[Compare]
  R --> P[Report]
  C --> CI[CI exit code]
Where to go next
- New user: finish the 30-second quickstart, then replace the mock adapter with your API.
- Integration author: use the adapter guide and Python extension API.
- Dataset owner: follow the dataset schema and benchmark manifest rules.
- CI maintainer: configure absolute, delta, relative, group, and coverage gates.
- Artifact consumer: validate the versioned run schema.
Scope by design
ragproof fits best when a deployed RAG endpoint must be tested from the outside and a reproducible CI decision matters. It is intentionally smaller than broad LLM experiment, red-team, observability, or hosted annotation platforms. Deterministic metrics require no model; optional judge metrics can use an OpenAI-compatible endpoint, including a locally operated one.